 ™
Ant's LingBot-World World Model Goes Open Source, Generating Nearly 10 Minutes of Video in One Take
Ant Group's embodied-AI unit Ant Lingbo released and open-sourced its general world model LingBot-World on Nov 17, publishing the code and model weights, with a single generation running nearly 10 minutes of coherent video.
What happened
LingBot-World follows the generative route of DeepMind's Genie 3: the model takes user action commands and generates visual feedback frame by frame; the Lingbo team said that as scale grew, the model began showing an understanding of spatial relationships, temporal continuity and physical laws — for example, water ripples responding to a duck's paddling, and an agent turning toward open floor instead of passing through a sofa.
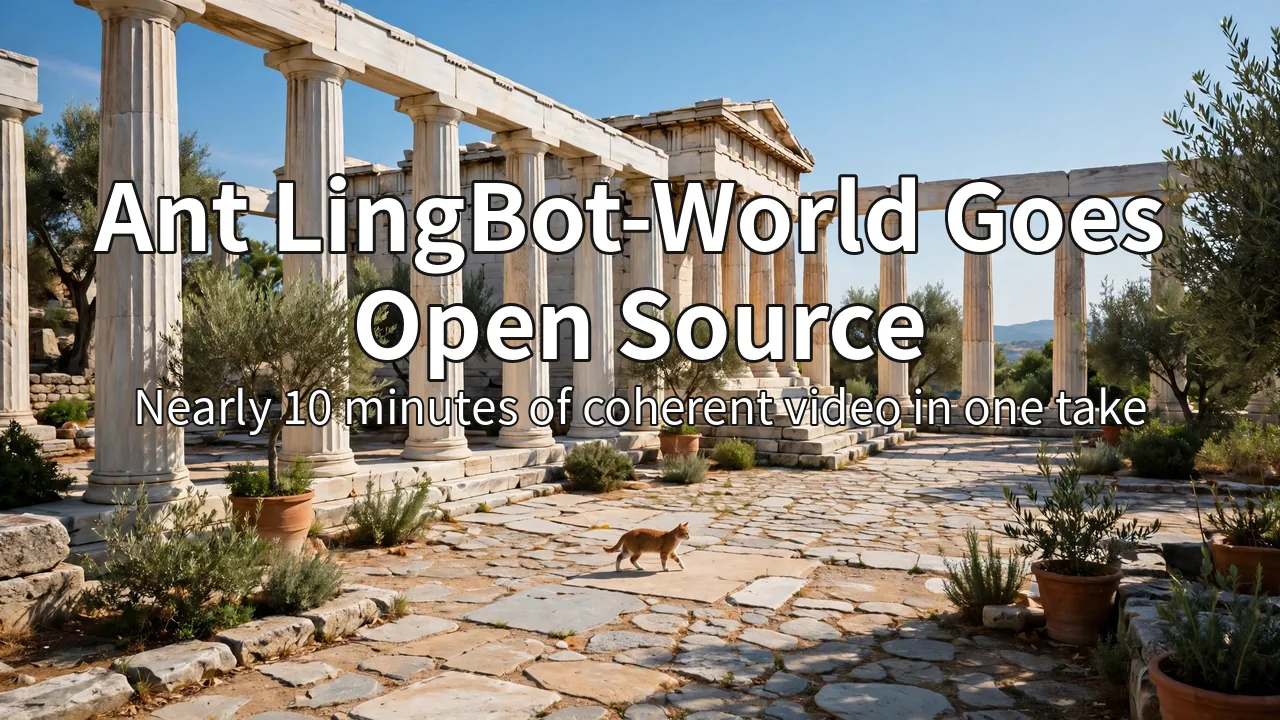
The demo video runs 9 minutes 20 seconds with no editing or splicing, starting in first person from a ruined ancient Greek temple and walking through city paths and a neoclassical building complex; InfoQ said the picture held fairly stable physical states and visual quality for nearly 10 minutes, likely a record for a single generation among current video and world models, while noting flaws in the final minutes, when the spatial relationship between buildings was briefly forgotten.
The model offers 720p resolution and real-time interaction, with the paper reporting latency under one second while generating 16 frames per second; it leads open models including Yume-1.5 and HY World-1.5 on VBench; in the same week, Lingbo also released and open-sourced the spatial-perception model LingBot-Depth and the embodied model LingBot-VLA.
Key facts
- Release: Ant Lingbo released and open-sourced the general world model LingBot-World on Nov 17, publishing code and weights with no tie to specific hardware or platforms
- Length: The demo video runs 9 minutes 20 seconds with no editing; InfoQ said a single generation of nearly 10 minutes of coherent video likely sets a current length record
- Interaction: The model generates visual feedback from user action commands; the paper reports latency under one second while generating 16 frames per second
- Benchmarks: Leads open models including Yume-1.5 and HY World-1.5 on VBench
- Data: Training data spans general video, game data and synthetic renders; game data was captured on an in-house platform aligning inputs with camera parameters, and synthetic data was generated with Unreal Engine
- Same-week releases: The spatial-perception model LingBot-Depth and the embodied model LingBot-VLA were released and open-sourced in the same week
- Paper: arXiv:2601.20540, submitted Jan 28, 2026
Why it matters
LingBot-World moves world models from video generation toward interactive physical simulation, with code and weights fully open; three models open-sourced in one week bring Ant Lingbo's embodied-AI platform out from behind the scenes.
Follow HIMIAO Horizon
No sign-up · Unsubscribe any timeNotifications
A ping on your phone or computer when the brief is out. No email needed.
Comments
Related
Today
Nov 19 Thursday- Brief
- GitHubGitHub Weekly Vol.6: 7 Projects Worth a Look This Week
Tested or read — weeklyAll →
- Quiz
- Call
Latest news
All →- Nov 19MAI Code 2 vs Claude Opus 5.5 and GPT-6.1 Sol: $0.50 Input vs $4, Promo Price Until May 2027
- Nov 18Study: Frontier Models Can Be Tricked Into Marking Civilian Targets
- Nov 18Nvidia Reaffirms Open-Source Strategy, Hugging Face Deal on Track
- Nov 17Klarna Launches AI Assistant That Shops, Books and Runs Errands
- Nov 18Palo Alto to Buy Applied Compute for $4.5 Billion in All-Stock Deal
- Nov 18NGINX2Root Exposed: Five 9.2-Severity Flaws Let Attackers Run Code on Nginx Without Logging In